Atlas
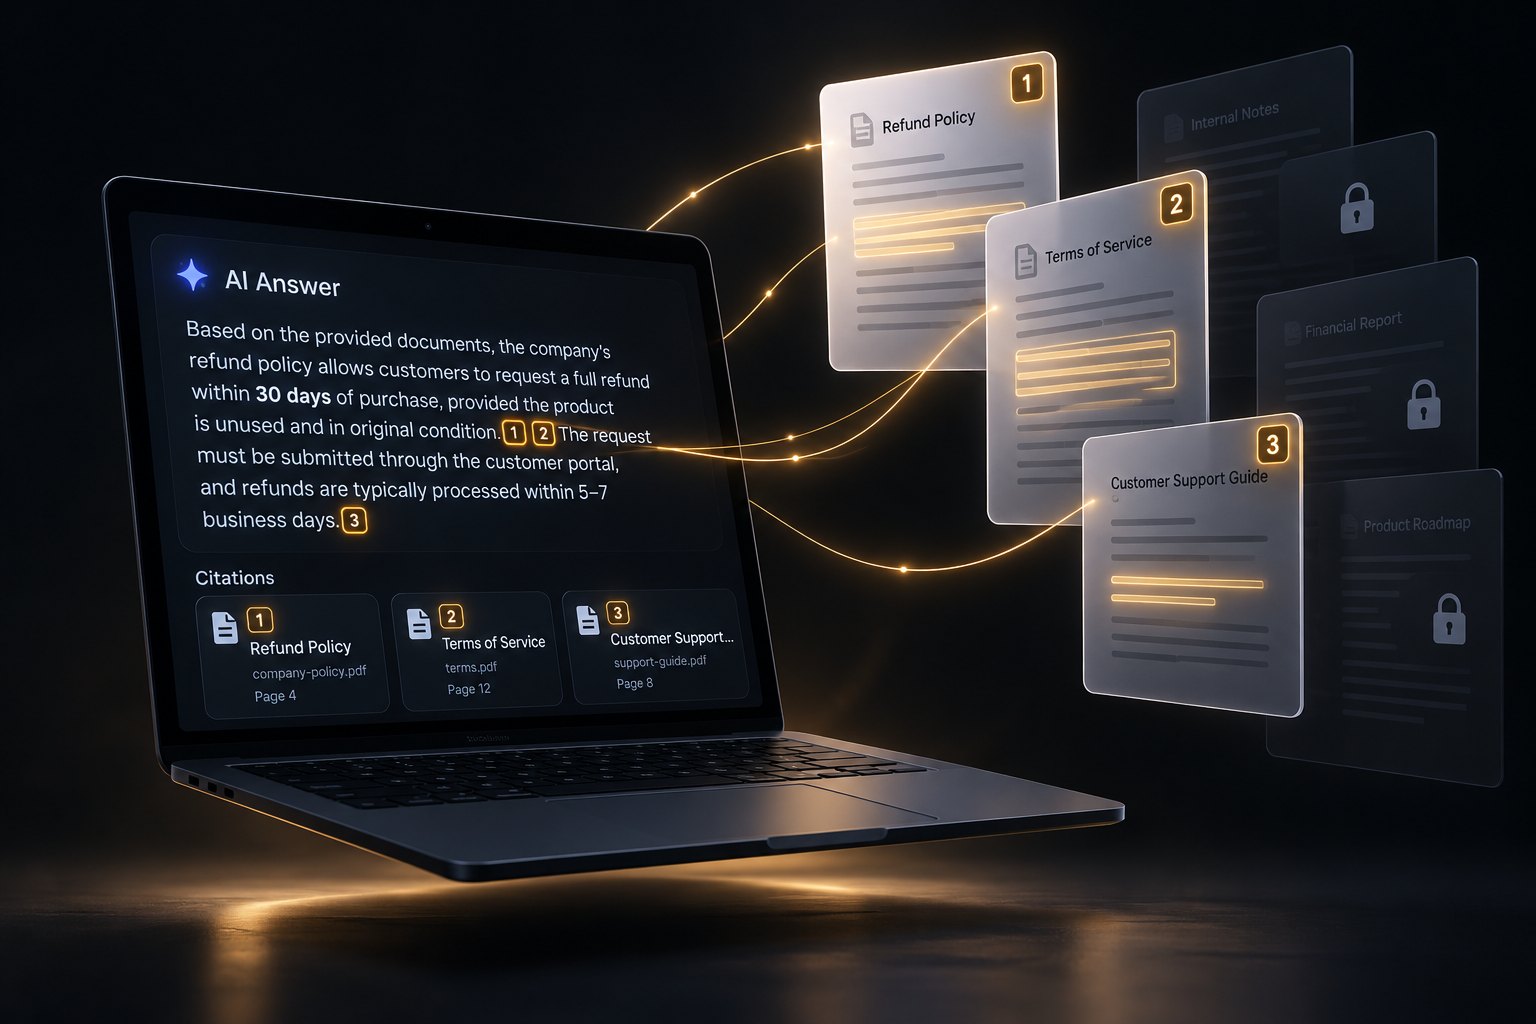
Company knowledge search that answers employees' questions with citations, using only the documents each person is allowed to see.
On the login page, "Log in as" Employee, HR, Finance, CEO or Admin (password: atlas-demo-password).
- Role
- Solo build: backend, retrieval, evals, web app
- Year
- Sep 2025
- Stack
- Python, FastAPI, PostgreSQL + pgvector, Redis, Next.js, LiteLLM + NVIDIA NIM, Claude, Docker + Caddy
The problem
Staff dig through HR, engineering, finance and security documents by hand. A basic upload-a-PDF chatbot ignores who may see what, makes answers up when the documents are silent, and is never measured.
How it works
What I built
- 01Hybrid retrieval inside one permission-filtered SQL query: pgvector HNSW, Postgres full-text and an exact policy-id lookup, merged with Reciprocal Rank Fusion and re-ranked by a cross-encoder. Forbidden text never reaches the model.
- 02Grounded answers with citations to document, page and section, streamed over SSE. Refusal thresholds tuned on the eval set cut wrong "not found" answers from 16.4% to 1.8%.
- 03A 64-question eval set (55 answerable, 9 that must be refused) runs through the same code path as the app, with an LLM judge and a CI gate. An MCP server lets AI agents search with the same permissions.
Try it yourself
Ask the company handbook a question, then switch who is asking. Watch the two searches, the merge, and the passages your role can't see disappear before an answer is written.
Signed in as
Or try
Retrieved and merged (Reciprocal Rank Fusion)
| Passage | keyword | meaning | fused |
|---|---|---|---|
| Travel policy p.4 §2.1 | 1 | 1 | 32.8 |
| Quarterly budget p.2hidden from Sales | – | 2 | 16.1 |
Answer
Hotel stays in metro cities are capped at ₹7,500 a night and booked through the travel desk. Travel policy p.4 §2.1
Runs in your browser with sample data. It follows the real product's rules; it isn't connected to it.
The result
Live at p1.kanav.space: ask, search, document viewer, admin, retrieval debugger and eval dashboards, with demo logins for five roles so you can watch answers change with permissions. On its eval set: Hit@1 of 1.0, faithfulness 0.998 and zero permission leaks (a small synthetic corpus). In production on a VPS with Docker Compose behind Caddy (automatic HTTPS, per-IP rate limits), CI on GitHub Actions and a nightly demo reset. Real AI through a self-hosted LiteLLM gateway: Nemotron models on NVIDIA NIM first, Groq and Cloudflare Workers AI as automatic fallbacks; the Claude API is supported too.
- permission leaks in every eval run
- 0
- permission leaks in every eval run
- question eval set, LLM-judged
- 64
- question eval set, LLM-judged
- API tests passing
- 182
- API tests passing